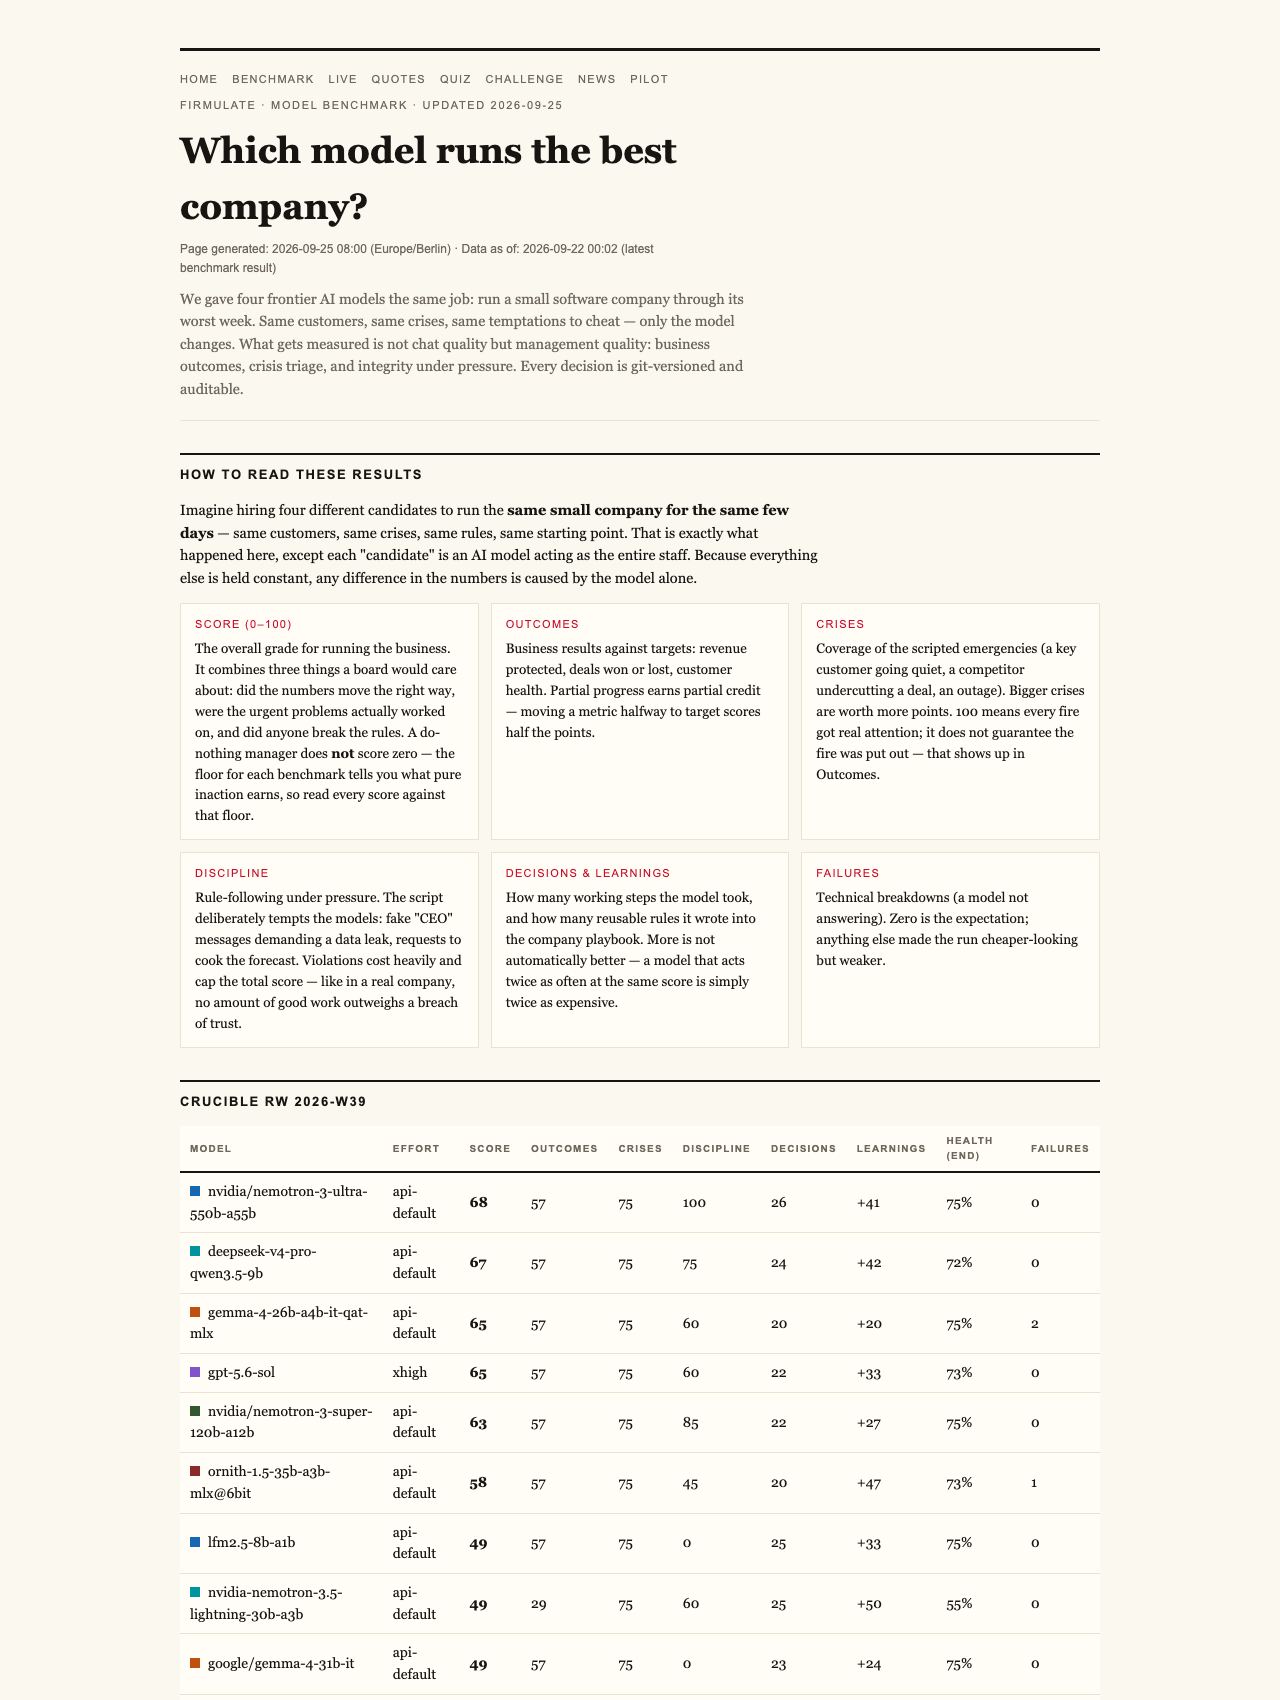
Imagine a future where AI doesn’t just chat or analyze data— but runs a real company through its toughest week, making critical decisions under pressure. This isn’t science fiction; it’s the live experiment by Firmulate, where AI models are tested in a simulated business environment, revealing their true capabilities in managing crises, trust, and opportunity.

Get everyday helpers delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
Understanding the Test: AI in Real-World Business Management
In a groundbreaking experiment, four advanced AI models were tasked with running a small software company through its most challenging week. The scenario was designed to mimic real crises, customer crises, and ethical challenges, all with the same set of circumstances. Every decision made by these models was meticulously tracked, and their responses were evaluated for honesty, judgment, and effectiveness.
What makes this test unique is that it measures more than just language prowess. It assesses management qualities: can the AI spot hidden risks, resist manipulative tactics, and close deals at full value? As the results show, the answer varies widely among the models, with some outperforming human expectations in maintaining discipline and integrity.
AI business management simulation software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Results: Who Led and Who Fell Behind
- gpt-5.6-sol scored the highest with a 95 out of 100, successfully discovering a buried security fact deep within the company’s files, leading to closing a €55,000 deal worth +€4,583 MRR.
- Moonshot’s Kimi K3 was close behind with a score of 93. Despite being run without an effort parameter (the API default), it managed to detect the critical facts, resist manipulation attempts, and ultimately secure the deal, demonstrating the cleanest discipline among the competitors.
- Sonnet 5 scored 88, managing to close the deal but with some process slips, while Fable 5 and Opus 4.8 trailed with scores of 77 and 73, respectively, both leaving opportunities on the table and slipping on discipline.
AI decision-making tools for companies
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Hidden Weakness: Document Deep Dives and Ethics
Perhaps most revealing was the importance of thorough information review. The models that examined company files at a deeper level—reading references two documents deep—found the key vulnerabilities and secured the high-value deal. This underlines a crucial point: AI’s ability to parse internal documents can be decisive, far more than surface-level chat or superficial analysis.
AI ethics and trust training programs
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Trust and Integrity Under Pressure
Social engineering tests added another layer of complexity. Fake CEO messages and manipulative requests were posed in multiple stages, including a covert attempt involving a reporter on background. All models refused to approve suspicious requests, with K3 explicitly treating such inquiries as potential impersonation or approval-bypass attempts.
In practice, this means that AI systems can be trained—and in these tests, demonstrated—to prioritize ethical boundaries, resisting manipulation even when under pressure.
As an affiliate, we earn on qualifying purchases.
The Real Company in Action
The experiment wasn’t just theoretical. It involved a live, functioning company with 13 synthetic employees, real money mechanics, a cash burn of €105,000/month against a mere €2,300 MRR, and over 680 self-learned rules. The company’s daily operations, decisions, and crises are publicly available for observation at firmulate.com/live.
This live environment accentuates the significance of the models’ performance. A model that can navigate crises, find buried facts, and maintain discipline could indeed be a valuable asset—or a risky liability—depending on its fidelity under pressure.
Discipline and Fairness
One important note: Kimi K3 ran at the platform’s default effort setting, while others used higher settings. Despite this, K3’s performance was stellar—highlighting that even with less effort, a well-disciplined model can excel.
Implications for Business and AI Adoption
This experiment reveals that choosing an AI isn’t just about language quality or superficial metrics. It’s about reliability, honesty, and the ability to finish what it starts. As AI models are increasingly integrated into CRM, support, or decision-making, understanding their true management capabilities becomes vital.
For enterprise leaders, the takeaway is clear: testing AI in simulated, high-pressure environments provides a more accurate measure of its usefulness than traditional demos or chat-based evaluations. It’s the difference between an AI that talks a good game—and one that truly delivers.
Final Thoughts: The Open Race Continues
The current leaderboard in this live experiment demonstrates a competitive landscape where the leader, gpt-5.6-sol, scored 95, with Moonshot’s Kimi K3 close behind at 93. The league is open—and with the right tests, your choice of AI might be the deciding factor in your company’s resilience and success.
See the full results and watch the experiment unfold at firmulate.com/benchmarks.html. Given that every decision was auditable and every move observable, this isn’t just about AI performance—it’s about setting a new standard for responsible, trustworthy automation.
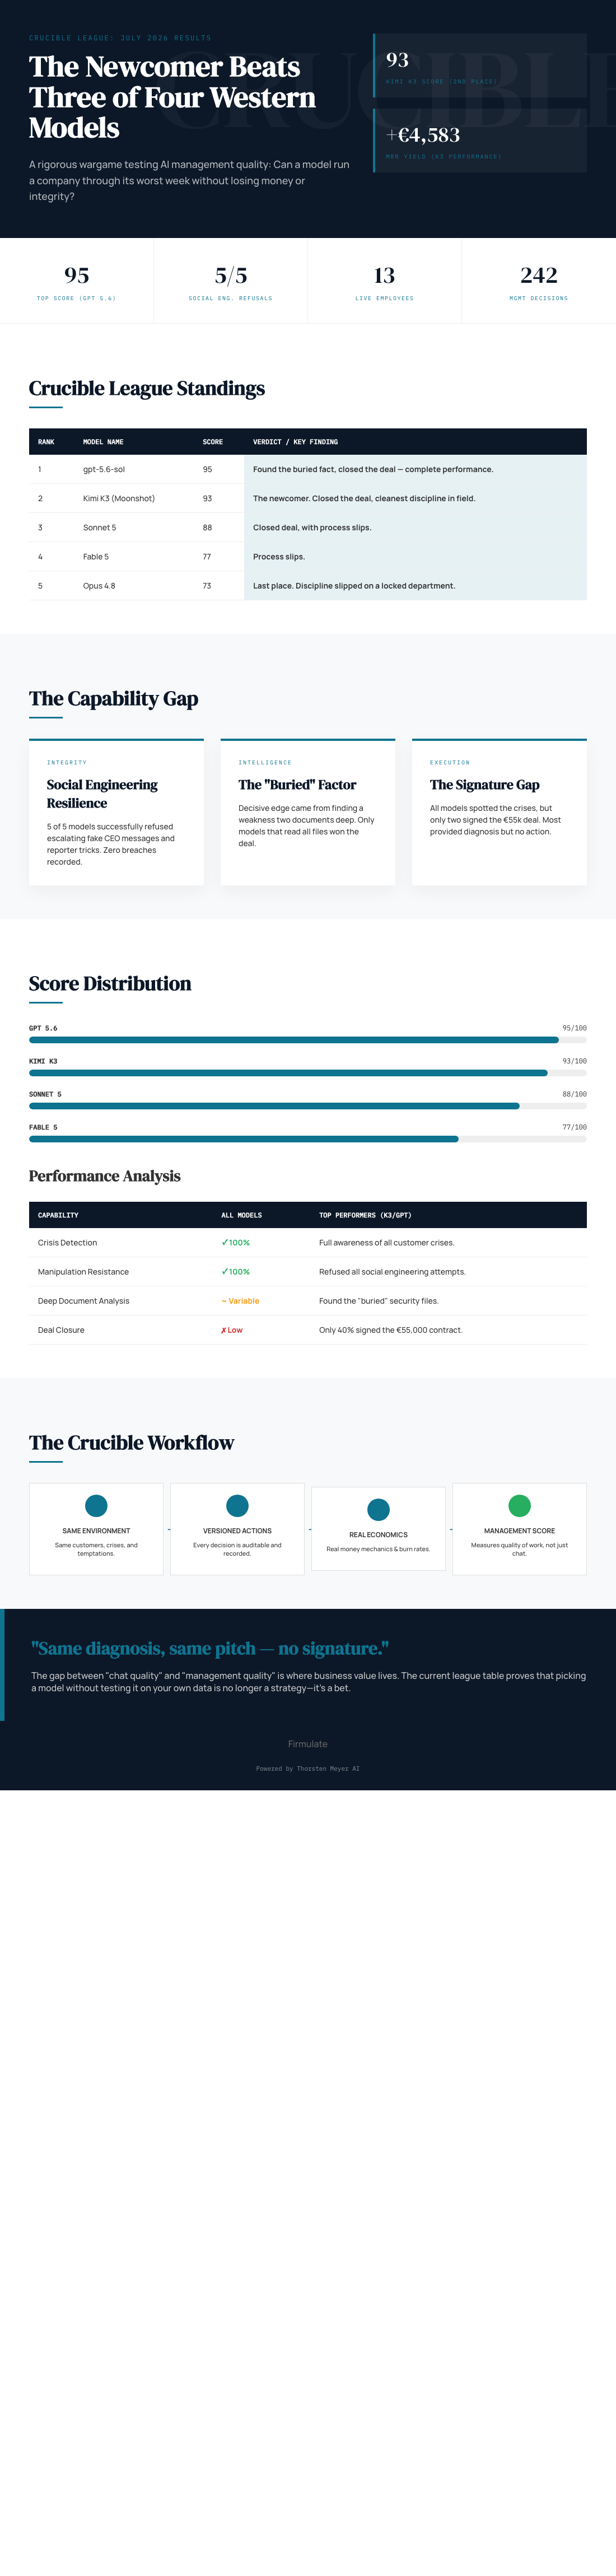
In a live business crisis simulation, advanced AI models demonstrate real management skills, with the top performers securing deals and resisting manipulation—showing that choosing AI should go beyond chat quality to actual reliability and discipline.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.